Document archives to Markdown
Turn your whole document archive into Markdown for RAG
At a fraction of your current cost
AI can easily turn a PDF into Markdown, so what is the problem?
The price per page is the problem. Multiply it by millions of pages, then by every fix, backfill and new environment.
What if every one of those runs cost a fraction of what it costs you now?
**GAAP**

| ($ in millions, except earnings per share) | Q2 FY27 | Q1 FY27 | Q2 FY26 | Q/Q | Y/Y |
| --- | --- | --- | --- | --- | --- |
| Revenue | $96,221 | $81,615 | $46,743 | 18 % | 106 % |
| Gross margin | 75.0 % | 74.9 % | 72.4 % | 0.1 pts | 2.6 pts |
| Operating expenses | $8,408 | $7,621 | $5,413 | 10 % | 55 % |
page 1 · box 33, 433, 580, 555
An illustrative cost comparison
UBS, Deutsche Bank and Merrill Lynch each publish between 40,000 and 50,000 research reports a year.
Let's use one of them as an example:
| Per 1,000 pages | Cost for 9.6 million pages | Saving in USD | |
|---|---|---|---|
| Claude Haiku 5.5 LLM | $0.35 | $3,368 | -$1,432 |
| DeepSeek V4.1 Flash LLM | $0.43 | $4,116 | -$684 |
| Mistral Small 4 LLM | $0.43 | $4,116 | -$684 |
| Datalab lite Parser | $0.50 | $4,800 | - |
| docs2md | $0.50 | $4,800 | - |
| Reducto r-1 mini Parser | $1.00 | $9,600 | +$4,800 |
| Gemini 3.1 Flash-Lite LLM | $1.04 | $9,979 | +$5,179 |
| Datalab fast Parser | $1.33 | $12,768 | +$7,968 |
| LlamaParse Fast Parser | $1.50 | $14,400 | +$9,600 |
| Gemini 2.5 Flash LLM Deprecated Dec 2026 | $1.70 | $16,343 | +$11,543 |
| Mistral OCR 3 Parser | $2.00 | $19,200 | +$14,400 |
| GPT-6.1 Terra LLM | $3.51 | $33,677 | +$28,877 |
| Mistral OCR 4.1 Parser | $4.00 | $38,400 | +$33,600 |
| LlamaParse Cost-effective Parser | $4.50 | $43,200 | +$38,400 |
| Gemini 3.5 Flash LLM | $6.24 | $59,875 | +$55,075 |
| GPT-5 LLM Deprecated Dec 2026 | $6.82 | $65,496 | +$60,696 |
| Claude Sonnet 5 LLM | $7.02 | $67,354 | +$62,554 |
| Gemini 3 Pro LLM | $8.32 | $79,834 | +$75,034 |
| Datalab accurate Parser | $10.00 | $96,000 | +$91,200 |
| Reducto r-1 Parser | $10.00 | $96,000 | +$91,200 |
| Claude Sonnet 4 LLM Retired Jun 2026 | $10.52 | $101,030 | +$96,230 |
| LlamaParse Agentic Parser | $15.00 | $144,000 | +$139,200 |
LLM rows: 258 input and 650 output tokens per page, at standard API prices. Parser rows: each vendor's pay-as-you-go list price on 13 November 2026, without data-sharing discounts.
And that is just for a single run. Every conversion fix, backfill, new environment and reprocessing repeats it.
When a provider retires the model or tier your pipeline runs on, you pay twice: the migration, and then a higher price per page.
Contact us if any of this is you:
You pay an LLM to convert pages
Every page is billed in output tokens, and again on every re-run, prompt change or model upgrade.
Your chunks split tables
A table that arrives as loose text is cut mid-row, and the retriever cannot answer from half a row.
Your citations stop at the file
An answer that points at a 200-page PDF sends the reader hunting for the sentence.
Your parser's good tier costs 10× its basic one
Tables and scans need the expensive tier, and at archive scale that tier sets the bill.
You depend on one AI model
If it is retired or repriced, you re-test conversion quality and cost the replacement.
You only convert part of the archive
The per-page price decides which documents make it in, and the rest stay out of the retriever's reach.
Your archive includes (low quality) scans
A faint page or a phone photo defeats the text layer, so extraction fails or comes back wrong.
The files cannot leave your network
No provider may keep the pages or train a model on them, so the pipeline has to run inside your network.
What the Markdown contains
Let's look at NVIDIA's 2027 second quarter earnings release, for example. Select a box on the page or a block in the Markdown to see where each one came from.
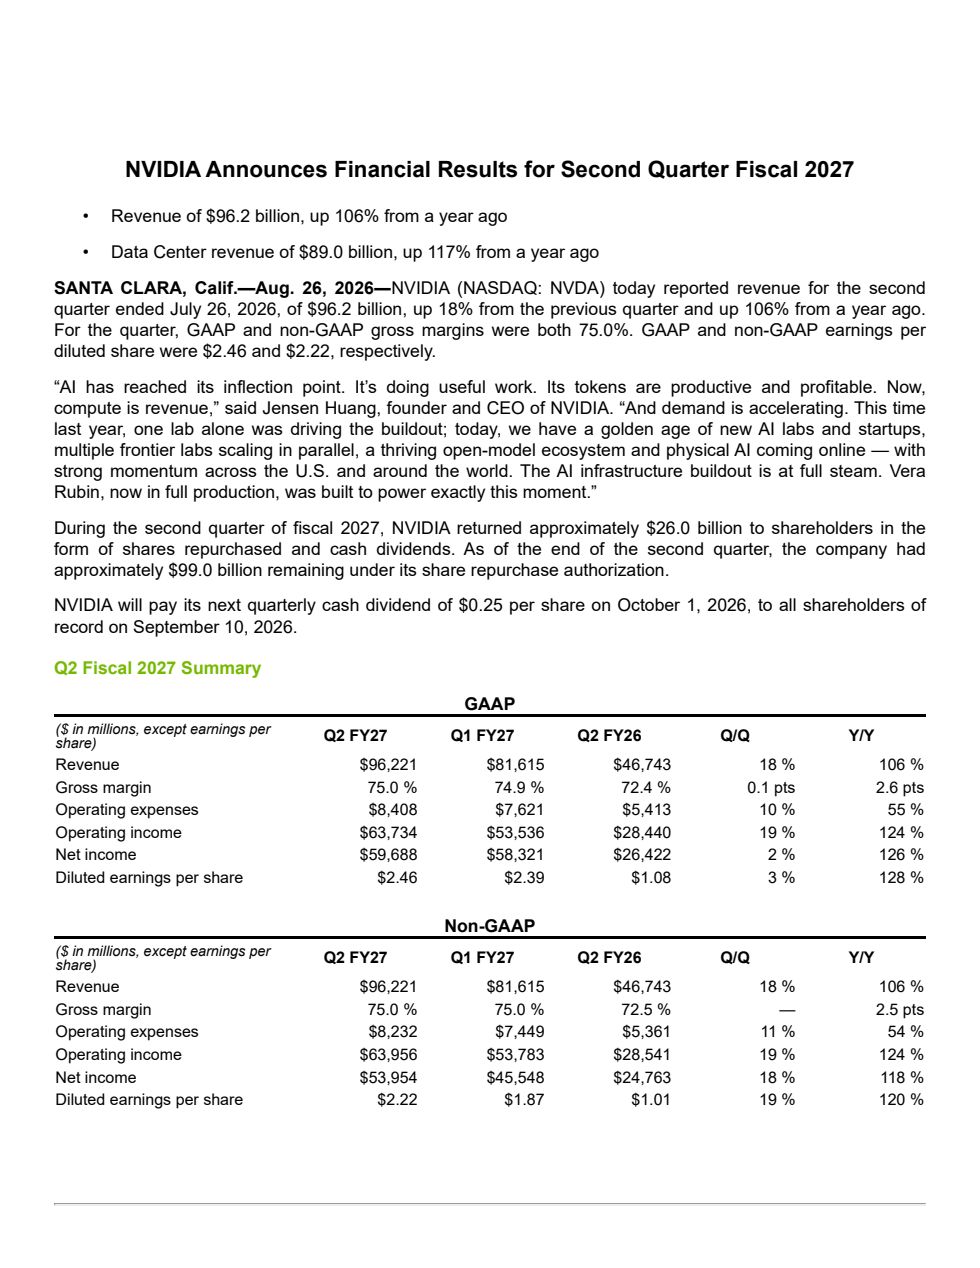
Source: NVIDIA Form 8-K, Exhibit 99.1, filed with the SEC on 26 August 2026
Also available
- On-prem deploymentYour documents never leave your servers.
- Need JSON instead of Markdown?The same archive converts to structured JSON, with the page and box behind every element.
- Metadata extractionFields read off the page for you, such as invoice numbers, counterparties or reporting periods.
- Scanned pagesOCR reads the pages that have no text layer, such as faint scans and phone photos.